

Microtensor @Microtensor_
A decentralized network for certified, specialized inference. Powered by multi-tiered architectures optimized for latency and cost. Weights public, API metered microtensor.cloud Joined August 2026-
Tweets124
-
Followers120
-
Following82
-
Likes429
𝗦𝗽𝗲𝗰𝗶𝗮𝗹𝗶𝘇𝗲𝗱 𝗶𝗻𝘁𝗲𝗹𝗹𝗶𝗴𝗲𝗻𝗰𝗲, 𝗯𝘂𝗶𝗹𝘁 𝗮𝗿𝗼𝘂𝗻𝗱 𝘆𝗼𝘂𝗿 𝗯𝘂𝘀𝗶𝗻𝗲𝘀𝘀. At 𝗠𝗶𝗰𝗿𝗼𝘁𝗲𝗻𝘀𝗼𝗿, we turn raw AI capability into a 𝗻𝗲𝘁𝘄𝗼𝗿𝗸 𝗼𝗳 𝗱𝗲𝗱𝗶𝗰𝗮𝘁𝗲𝗱 𝘀𝗽𝗲𝗰𝗶𝗮𝗹𝗶𝘀𝘁𝘀 that fit seamlessly into the 𝘄𝗼𝗿𝗸𝗳𝗹𝗼𝘄𝘀 𝘆𝗼𝘂𝗿 𝘁𝗲𝗮𝗺𝘀 𝗮𝗹𝗿𝗲𝗮𝗱𝘆 𝘂𝘀𝗲. The smartest way to run AI in your business isn't to lean on generic, oversized models. 𝗜𝘁'𝘀 𝗽𝗿𝗲𝗰𝗶𝘀𝗶𝗼𝗻. We bridge the gap between frontier intelligence and the 𝗼𝗽𝗲𝗿𝗮𝘁𝗶𝗼𝗻𝗮𝗹 𝘄𝗼𝗿𝗸𝗳𝗹𝗼𝘄𝘀 that actually run your company. By mapping 𝘁𝗮𝘀𝗸-𝘀𝗽𝗲𝗰𝗶𝗳𝗶𝗰 𝗺𝗼𝗱𝗲𝗹𝘀 to your day-to-day operations, Microtensor lets your teams automate everyday work 𝗿𝗲𝗹𝗶𝗮𝗯𝗹𝘆, 𝗽𝗿𝗶𝘃𝗮𝘁𝗲𝗹𝘆, 𝗮𝗻𝗱 𝗮𝘁 𝗮 𝗳𝗿𝗮𝗰𝘁𝗶𝗼𝗻 𝗼𝗳 𝘁𝗼𝗱𝗮𝘆'𝘀 𝗰𝗼𝘀𝘁. 𝗡𝗼 𝗱𝗶𝘀𝗿𝘂𝗽𝘁𝗶𝘃𝗲 𝗼𝘃𝗲𝗿𝗵𝗮𝘂𝗹𝘀. 𝗡𝗼 𝗯𝗹𝗼𝗮𝘁𝗲𝗱 𝗔𝗣𝗜 𝗯𝗶𝗹𝗹𝘀. Discover the smartest way to run AI in your business. Book a demo 👉 microtensor.cloud/sales #Microtensor #AI #Bittensor bittensor:native #Subnet #EnterpriseAI #WorkflowAutomation #TechInfrastructure

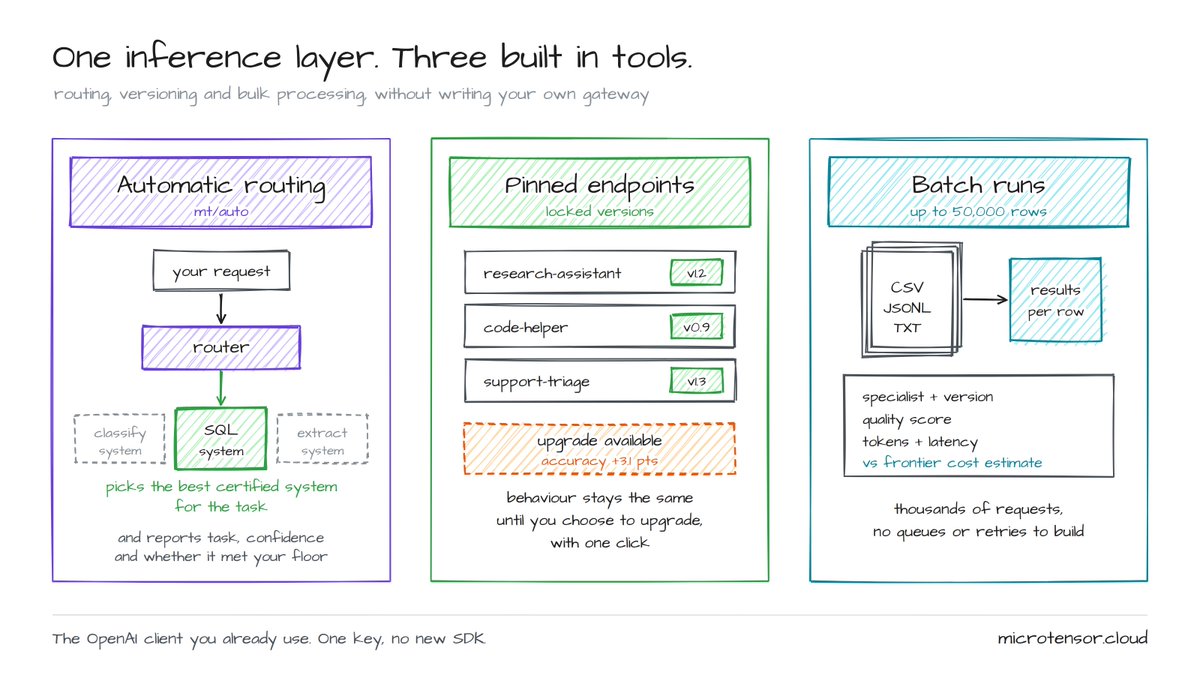
Running LLMs in production takes more than calling a model. Teams have to decide which model handles each request, keep that model's behaviour stable as it changes, and process large volumes without failures going unnoticed. In practice, that means writing and maintaining their own routing logic, version tracking, retry queues and logging, just to know which model answered, how well, and at what cost. Microtensor solves this with three tools built into a single drop in inference layer. Product teams can hand off routing, versioning and bulk processing, and get predictable performance with clear quality and cost data on every request. 𝗔𝘂𝘁𝗼𝗺𝗮𝘁𝗶𝗰 𝗿𝗼𝘂𝘁𝗶𝗻𝗴 The need: deciding which model should handle each request. How: swap the base URL in your OpenAI client and send `mt/auto`. Requests matching a certified task go to a certified specialist, and everything else goes to a general model. What you get: every response reports the task detected, the specialist that answered, its confidence, and whether it met your quality floor. 𝗣𝗶𝗻𝗻𝗲𝗱 𝗲𝗻𝗱𝗽𝗼𝗶𝗻𝘁𝘀 The need: model behaviour that changes under a live product. How: lock a named endpoint to the specialist versions you choose, each with its own quality bar, content log and traffic. What you get: behaviour that stays the same until you upgrade. When a better specialist is certified, you see the accuracy change and upgrade with one click. 𝗕𝗮𝘁𝗰𝗵 𝗿𝘂𝗻𝘀 The need: running thousands of requests without building queues and retries. How: upload a CSV, JSONL or TXT file of up to 50,000 requests and run it through routed inference or a pinned endpoint. What you get: every row comes back with the specialist and version, quality score, tokens and latency, plus a summary against the estimated cost on a frontier model. Docs: microtensor.cloud/docs/api/getti… #AIInfrastructure #SmallLanguageModels #Developers #Bittensor bittensor:native #Subnets
How the listening device got installed at OpenAI
Most AI workloads are over provisioned. Teams route almost every request to a frontier model. Fixing a typo and debugging a checkout failure run on the same parameter heavy network, at the same latency and the same premium price. For the bulk of production traffic, that capacity goes unused. At Microtensor, we are building a task calibrated inference API to close that gap. 𝗛𝗼𝘄 𝗶𝘁 𝘄𝗼𝗿𝗸𝘀 • Drop in: change the base URL and API key in the OpenAI client you already use. No new SDK. • Identify: a lightweight, calibrated router classifies each request by task, such as classification, decisions or structured extraction. • Serve: a certified specialist model, fine tuned for that task, answers the request. Only when the router's confidence falls below your quality floor does the request escalate to a frontier model. 𝗪𝗵𝗮𝘁 𝘁𝗵𝗲 𝗿𝗲𝘀𝗲𝗮𝗿𝗰𝗵 𝘀𝗵𝗼𝘄𝘀 • Specialists close the gap. An adapted small model recovered 89.7% of frontier performance at 4% of the cost (Carnegie Mellon University). • Routing preserves quality. Quality aware routing cut calls to the large model by up to 40% with no drop in response quality (Hybrid LLM, ICLR 2024). • Smaller footprint. Task specific models use orders of magnitude less energy per query than general purpose generative models (Luccioni, Jernite and Strubell, ACM FAccT). The result: frontier accuracy where the task demands it, and specialist cost, speed and efficiency everywhere else. Coming soon. Follow our progress at microtensor.cloud #AI #SmallLanguageModels #LLM #AIInfrastructure #Developers #Bittensor bittensor:native #Subnets

Last week the Microtensor team rolled out a complete platform redesign for a fresh look and feel, and upgraded our entire miner mechanism to make model certification more rigorous and fairer for miners and validators. 🛠️✨ This week our focus shifts to user facing tools, making sure our end users can put certified specialists to work from day one. We're starting with an OpenAI compatible inference API with task aware routing. Why now? In recent weeks OpenAI launched GPT 6 Astra, xAI launched Grok 4.7, Anthropic launched Claude Opus 5.5 and Google announced Gemini 4 Argon. Deciding which model is the smartest is no longer the real problem. The real question is which model should handle this particular task. 🧠 "Fix a typo" and "debug our checkout failure" sit at opposite ends of the difficulty spectrum. Yet most systems send both to massive generalist models, paying frontier inference costs for simple tasks that a compact specialist resolves at a fraction of the compute. Here's what's coming to Microtensor: 1️⃣ Drop in compatibility: point the OpenAI client you already use at Microtensor. One API key, no new SDK to learn. 2️⃣ Task identification: a calibrated router reads each incoming request and classifies the task, whether text classification, a critical decision or structured data extraction. 3️⃣ Specialist inference: each task is served by the certified specialist best suited for it, escalating to a frontier model only when the router's confidence falls below your quality floor. 🎯 The result? Frontier level accuracy, lower latency and a fraction of the inference cost, just by switching the base URL and key in your existing code. Stay tuned. The future of decentralised inference is lean, smart and efficient. 🚀 microtensor.cloud #Bittensor #Subnet bittensor:native #AIInfrastructure #SLMs #LLMs #Developers
🔹 Frontier models only when needed: sending easy queries to a small model and escalating hard ones cut large model calls by up to 40% with no quality drop (Hybrid LLM, ICLR 2024), and matched GPT 4 at up to 98% lower cost (FrugalGPT, Stanford). Frontier level accuracy on your task. A fraction of the cost, energy and carbon. Running where you choose. That is the case for specialised SLMs, and it is what Microtensor delivers. Before you scale, calculate what every query costs. Our whitepaper: microtensor.cloud/research
🔹 Less energy per query: task specific models are orders of magnitude cheaper to run than general purpose generative models, even at equal size (Luccioni, Jernite and Strubell). The hungriest frontier LLMs use over 29 Wh per long prompt, 65x the most efficient (Jegham et al.). 🔹 Independence: a specialist fits on a single GPU, so it can run on your own infrastructure. When Moxie's servers shut down, the robots that kept working were the ones owners moved onto open source software they ran themselves (PIRG)
In December 2024, families who paid $799 for Moxie, an AI companion robot for kids, learned it was about to stop working. Every conversation ran on large language models in the cloud (OpenAI API). When the funding ran out, the servers went dark (Axios). 🧵 Moxie is an extreme case, but the lesson applies to every AI product. When every interaction depends on a large model in someone else's cloud, inference cost becomes the cost of your business. As one report put it, "LLMs are not cheap to run" (Aftermath) axios.com/2024/12/10/mox…
@MiraaCrypto @opentensor In the US/UK, adoption hits walls like HIPAA or financial privacy laws that block sending data to public cloud APIs. In regions like Africa or Asia, the policy is similar but limited by cross-border bandwidth to Western data centers
bittensor:native The next wave of AI adoption will not be decided where AI is already abundant. In the US and UK, putting AI into a hospital or a bank means clearing layer after layer of regulation. Growth is moving to Africa, Asia and Latin America. @opentensor #Bittensor #Subnets

@ledgersable @opentensor Good question @ledgersable. Validation and serving are separate. Validators certify each system once on reference hardware, anywhere on the network. The certified model runs locally, even offline, so new users in a region add no validation load. It scales with tasks, not users.
Alex Zverianskii @alexML
938 Followers 3K Following MTS @withmartian • ex Principal MLE @gett 15+ years in AI/NLP • 3x founder (1 exit)
Naomi @hfgbtrb
242 Followers 216 Following Living simply, finding joy, and appreciating every connection
tribbit @iamtheloraxnow
32 Followers 59 Following Arms dealer for the Web3 x AI revolution, Subnet Summer x Medulla Labs evangelist, and former OTF acolyte.
goodluck @cpupool
133 Followers 2K Following
Dewey @Deweythe2
2K Followers 5K Following SaaS Growth | Helping B2B SaaS companies scale | Growth systems & acquisition
macrozack (τ, τ) �... @macrozack
2K Followers 826 Following Builder @bitstarterai Director @MacrocosmosAI Editor @taotimesdotai Convening Bittensor's @ExploitSummit 🧩 https://t.co/9k3wunNQwr 🚀
Ugo Chiya τ_τ Al @ugo_chiya21
2K Followers 2K Following Bittensor Alpha || Decentralized AI Insights || Breaking down $TAO, Subnets & Opportunities || Machine Learning Enthusiast || High Ticket Closer || Remote Sales
Invest With Doc - MD/... @InvestwitthDoc
62 Followers 2K Following Stocks, Crypto, Finance | MD/MBA | Exclusive Content → https://t.co/zxtlobSDLS
Tao Outsider @TaoOutsider
5K Followers 696 Following Zooming-out $TAO Bittensor. Writing about the ecosystem and subnets. Marketing at Bitstarter.
Rado | τsc @RadoTsc
2K Followers 892 Following Ex R.E turned Bittensor maxi | Mining & staking subnets | Founder https://t.co/6lqaR5GpRt | https://t.co/Whyy9NacCy
Tanya Stanley @TStanley18_
2K Followers 5K Following
Osano AI @osanoai
16 Followers 139 Following Osano AI by @Osano, a leader in data privacy. Open source LLMs, agent platforms like Hermes, AI trends. https://t.co/AG9bm7rNSu
Kevin Vint @vint_kevin
149 Followers 2K Following Hold yourself responsible for a higher standard than anybody expects of you. Never excuse yourself.---Henry Ward Beecher, clergyman---
Hajarah Ali @ali_hajarah
1K Followers 144 Following 🔖𝐁𝐨𝐬𝐬 𝐥𝐚𝐝𝐲, 𝐀𝐥𝐥𝐚𝐡 𝐟𝐢𝐫𝐬𝐭 🤲, 𝐈 𝐥𝐨𝐯𝐞 𝐦𝐢𝐧𝐝𝐢𝐧𝐠 𝐦𝐲 𝐛𝐮𝐬𝐢𝐧𝐞𝐬𝐬💚
Xavier @XReyRobert
4K Followers 7K Following Platform engineering, AI, coding & architecture Account Technical Leader @IBM Chief Agent Executive @SaturdAIfevr
BROWN @BrownVerse
1K Followers 2K Following NFT Vanguard • Meme Tactician • Prolific Project Promoter • HighVelocity Post Raider.
Ariel Rowland @bfjvv47835264
6 Followers 234 Following

TaoBubbles @Tao_Bubbles
61 Followers 246 Following Live bubble map of every Bittensor subnet. Prices, market caps and moves from 1H to 1M, updated in real time.

Robinhood Army @fanrobinhood
260K Followers 16K Following #Parody Account. Hunting memes & gems on Robinhood Chain • Memes .DM for business. Not associated with @RobinhoodApp .
江 @ilr3W7IkKl86715
5 Followers 154 Following
KV Moonshot @evildexcoin
29 Followers 168 Following Trading Company, Advisor https://t.co/iaOIAIJocO

Drayke69 @DaddyS20416
20 Followers 153 Following

wallscaler @thewallscaler
339 Followers 370 Following Up walls, then up stacks. Building @cathedralhq: sandboxed compute for agents, graders and miners. Prev: Sr PM @Microsoft, @BBCRD.
Stein ⚚ @Baron_of_PH
453 Followers 148 Following Builder by day degen by night | strategic marketing nerd | PM: @polariscloudai | Your Devs favourite Dev
Ovidius @gawblimeyguvnor
316 Followers 1K Following

SubnetRadar @SubnetRadar
39 Followers 102 Following Scanning the Bittensor universe $TAO 🛰️ Your trusted source for Subnet performance, innovation & news. #Bittensor #Subnets → Join the radar.
τony τao @tony_tao_tucker
107 Followers 366 Following Investing, sourcing and structuring property opportunities for 15 years 📈 Now active in Bittensor. Open to conversations with subnet owners & teams.
CryptoCoinz @CryptoCoinzTeam
513 Followers 3K Following
Verathos @verathos_ai
562 Followers 23 Following Decisions in one call. Open-weight decision models on Bittensor SN96: a probability for every option, signed by the miner that answered.

P&E 炼游A....|蓝�... @bnb1620956
6K Followers 3K Following #Web3 资讯分享| NFT |炼游新人|撸毛达人|项目早期挖掘者| Play and earn社区创始人 @PE_Coummunity | 接 KOL宣发📩商务合作|社区DC https://t.co/S2hSXsiWwW | @LastOdyssey_io Warlord
Hot Soice @HotSoicecrjc
14 Followers 241 Following
⋆。°✩ ₿iττa... @AIFintechEng
206 Followers 259 Following Building and mining on Bittensor | Active Polymarket trader | Deep in AI infrastructure, DePIN, and global macro/crypto trading.
Cyril @Cyril1276838
8 Followers 44 Following
τouch @bittensortouch
166 Followers 388 Following τop subnet news, posted as soon as they come out ⚡🚨 $TAO
@Nykola @Nykola_T
24 Followers 91 Following Co-founder @tensiaFDN The bridge between Human & Decentralized AI. 🧠 Demystifying the Bittensor ecosystem. Making the invisible understandable. 📚

inevitablezn @kzncharou
149 Followers 3K Following

Ricky - τ Flows @TAOFlows
2K Followers 270 Following Computer Scientist, Tech Enterprise Sales and Bitcoin veteran. Onboarding people into bittensor one flow at a time.

陈孙华 @chensunhua3
1 Followers 161 Following
fschultze @fede_schultze
337 Followers 343 Following
Asahi |🚢 @zx23884486
486 Followers 7K Following "Empty your mind. Be formless, shapeless like water. Pour into cup, it becomes cup; bottle, bottle; teapot, teapot. Water can flow or crash. Be water, my friend
Macrocosmos @MacrocosmosAI
8K Followers 22 Following Building distributed intelligence on Bittensor. SN1, 9, 13 https://t.co/LizGMGPFh4 https://t.co/weDmtZxH4V
Apex・SN1 @Apex_SN1
911 Followers 13 Following Hillclimbing intelligence. Game-theoretic AI on #Bittensor, powered by @MacrocosmosAI
Alex Zverianskii @alexML
938 Followers 3K Following MTS @withmartian • ex Principal MLE @gett 15+ years in AI/NLP • 3x founder (1 exit)
Exploit Summit @ExploitSummit
2K Followers 59 Following Bittensor's Native Conference. September 28-29, 2026. New City Gas, Montreal, Canada. https://t.co/KKVWPFQUtl
Nous Research @NousResearch
285K Followers 31 Following A bunch of nerds making progress https://t.co/vrD0aDIGDQ
tribbit @iamtheloraxnow
32 Followers 59 Following Arms dealer for the Web3 x AI revolution, Subnet Summer x Medulla Labs evangelist, and former OTF acolyte.
Alchemist - τ @SubnetSummerT
3K Followers 2K Following 🛡️ Building an honest Bittensor validator @SubnetSummerTAO 🗳️ Education · Discourse · Democracy = https://t.co/kJ7lNmpKbV 🎤 Convening @ExploitSummit & @proofoftalk
goodluck @cpupool
133 Followers 2K Following
macrozack (τ, τ) �... @macrozack
2K Followers 826 Following Builder @bitstarterai Director @MacrocosmosAI Editor @taotimesdotai Convening Bittensor's @ExploitSummit 🧩 https://t.co/9k3wunNQwr 🚀
Dendrite @DendriteHQ
704 Followers 31 Following Scaling decentralized AI on Bittensor. Owner: SN114 @SomaSubnet. Co-builders: SN3 Teutonic, SN66 Conjectures, SN97 Albedo. Mining: many.
DIABLO @ledgersable
2K Followers 1K Following ⚡ Crypto’s silent storm 🕶️ Mountains in the visor, chaos in the wallet 🔥 When I enter the chart, candles turn red 💎 Not here to hodl… here to rewrite the
τony τao @tony_tao_tucker
107 Followers 366 Following Investing, sourcing and structuring property opportunities for 15 years 📈 Now active in Bittensor. Open to conversations with subnet owners & teams.

Subnet Summer @SubnetSummerTAO
3K Followers 323 Following The Town Square of Bittensor Validator: https://t.co/IxXzXadjrO TG: https://t.co/tuwblNLhy8 YT: https://t.co/t4K3McKJH3
Nepher Robotics @nepher_robotics
701 Followers 54 Following Robot Learning & AI | NVIDIA Omniverse | NVIDIA Inception | Bittensor SN49
Harnyx AI @harnyx_ai
365 Followers 1 Following Deep research as a commodity. Faster, cheaper, traceable research — produced by a competitive swarm of miners on Bittensor SN67.
Ditto @heydittoai
2K Followers 148 Following Stop starting over. Do more with Ditto. AI that remembers your context and gets things done across your apps.
Gordon Frayne @gordonfrayne
22K Followers 11K Following Helping investors build wealth with AI, crypto & DeFi. Frameworks & strategies for long-term wealth. 🎥 YouTube: 13K+ subscribers
TaoWifHood @TaoWifHood
360 Followers 103 Following The first $TAO paired meme coin on Robinhood. Hold $TWIF, Earn $TAO. TG: https://t.co/ixbDB7dbcl 0x78E80660E9A832F60dBfad1462eE7d9aA3c9BC34
SUBNET | Degen @Thesubnetdegen
466 Followers 751 Following Proud #sn93 Bitcast miner☝ All in on subnets #Tao I make good calls but always DYOR🧠
Invest With Doc - MD/... @InvestwithDoc
9K Followers 2K Following Options, Crypto, Stocks, Finance | MD/MBA | $MSTR & $ASST |
Ugo Chiya τ_τ Al @ugo_chiya21
2K Followers 2K Following Bittensor Alpha || Decentralized AI Insights || Breaking down $TAO, Subnets & Opportunities || Machine Learning Enthusiast || High Ticket Closer || Remote Sales
Tao Outsider @TaoOutsider
5K Followers 696 Following Zooming-out $TAO Bittensor. Writing about the ecosystem and subnets. Marketing at Bitstarter.
Mark Jeffrey @markjeffrey
74K Followers 2K Following Partner at Bittensor Fund @stillcorecap Hash Rate podcast
Punisher ττ ✠ @CryptoZPunisher
9K Followers 2K Following Biττensor τ_acc $TAO Bittensor OG since 2022. Creaτor of Magellan the Biττensor mind map https://t.co/rm698HOGPu
Burning Lake @BurningLakeRock
5K Followers 20 Following Rock/folk quartet from Western Switzerland. New single 'Little Man' out today. View the lyric video on YouTube: https://t.co/wVmY6KX4t8
Jared Lawrence @Beyondfinancee
3K Followers 692 Following Founder of Beyond Finance - Helping others build wealth within the Bittensor Eco-system. 👇 For Investors & Builders
Rado | τsc @RadoTsc
2K Followers 892 Following Ex R.E turned Bittensor maxi | Mining & staking subnets | Founder https://t.co/6lqaR5GpRt | https://t.co/Whyy9NacCy
Reef @Rhef_12
194 Followers 29 Following
Tanya Stanley @TStanley18_
2K Followers 5K Following
Beyond Finance Commun... @BeyondFinanceCo
135 Followers 166 Following A Bittensor collective. We back builders with capital, ecosystem knowledge, and the inner game. Finance is the vehicle, not the destination.
Solana @solana
4.2M Followers 4K Following The high performance network powering internet capital markets, payments, AI agents, stocks, memes, and crypto apps.
SEBY (gpu/acc) @sebyrubino
2K Followers 333 Following Accelerated Uncensored Inference @thinkinstant Permissionless GPU Loans @zipcodenetwork Ex: Compound and Maple
Hunter T. @hunter_tensor
275 Followers 213 Following Jan, the Co-Founder & COO at @DendriteHQ. Leading our mining ops & helping build Bittensor subnets. SOMA | Teutonic | Albedo | Conjectures

mogmachine (ττ) @mogmachine
10K Followers 672 Following founder: @taostats co-founder: @hippius_cloud @vidaio_ @blockmachine_io, @say_gm_ 'putas e vinho verde'
Crucible Labs @CrucibleLabs
4K Followers 92 Following Dedicated to advancing decentralized AI Download Crucible Wallet https://t.co/Verdyo1Tvb
Stillcore Capital @stillcorecap
5K Followers 3 Following Bittensor (TAO) Fund @jason @markjeffrey @rob_svrn
Instant Inference (gp... @thinkinstant
332 Followers 9 Following Lightning Fast Uncensored Inference

Mentat Lend @MentatLend_
435 Followers 3 Following The first lending market for Bittensor Subnet Tokens.
subnet Sam @buildwithsamp
890 Followers 430 Following Tech Partner @ Crucible Labs. a WOMBO og. Breaking down Bittensor, one baguette at a time
BROWN @BrownVerse
1K Followers 2K Following NFT Vanguard • Meme Tactician • Prolific Project Promoter • HighVelocity Post Raider.

taostats τ @taostats
11K Followers 41 Following Official Block Explorer & Gateway to Bittensor. Trusted by thousands daily to Stake TAO and Alpha, track portfolios, access historical data and so much more.You might like


















